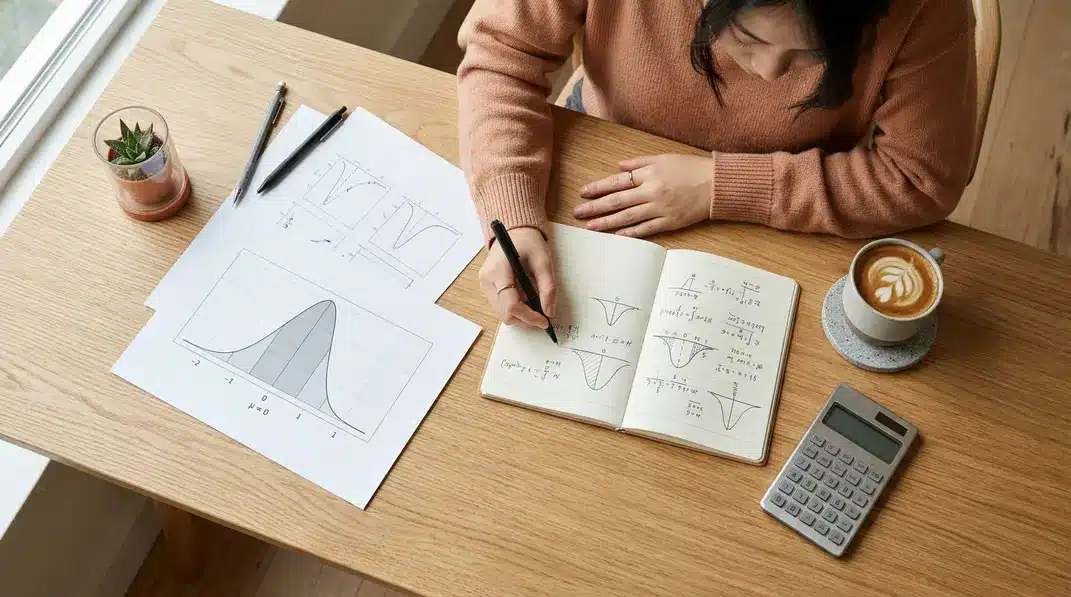
I still remember the first time I stared at a massive dataset with variables ranging from tiny decimals to millions. It was totally annoying trying to figure out which feature actually mattered! 😊 If you’ve ever felt overwhelmed by messy data or wondered how to accurately compare test scores from completely different classes, you are definitely not alone. That’s where the magic of the Linear Z transformation comes in.
What Exactly is a Linear Z? 🤔
To be honest, the term “Linear Z” (often simply referred to as Z-score standardization) sounds way more intimidating than it actually is. In the world of statistics and data science, it is just a mathematical method used to linearly transform your data. The goal? To ensure your data has a mean (average) of zero and a standard deviation of one.
Think of it like translating various foreign currencies into one universal currency so you can easily figure out the true value of things. When you apply a linear Z transformation to a dataset, you aren’t distorting the distances between the points in a non-linear way; you are simply shifting and scaling them.
Standardization doesn’t change the underlying shape of your data distribution. If your raw data is heavily skewed to the right, your Z-scores will also be heavily skewed to the right. It’s a purely linear shift!
Comparing Raw Data vs. Transformed Data
| Feature Type | Raw Data Example | After Linear Z Transformation |
|---|---|---|
| Annual Income | $35,000 – $250,000 | -1.5 to +2.5 |
| Customer Age | 18 – 85 years | -2.1 to +1.8 |
| House Price | $150,000 – $1.2M | -1.2 to +3.1 |
As you can see in the table above, incredibly large and differing scales are neatly compressed into a standard, manageable range. This makes it incredibly simple to feed this data into machine learning algorithms or run statistical analyses without one massive variable throwing everything off balance.
The Math Behind the Magic 🧮
Now, let’s get our hands a little dirty with some math. Don’t worry, I promise to keep it super simple! We use a specific, straightforward linear formula to calculate the Z-score for any given data point. Once you understand this formula, you’ll be able to manually convert any dataset yourself.
📝 The Linear Z Formula
Z = (X – μ) / σ
Here is the breakdown of what those symbols actually mean. X represents your individual raw score. The Greek letter μ (mu) stands for the mean (average) of the entire population, and σ (sigma) represents the standard deviation. By subtracting the mean and dividing by the standard deviation, you discover exactly how many standard deviations a score is from the average.
📝 Practical Calculation Example
Let’s imagine you just took a difficult math exam.
- Step 1: Your personal test score (X) is 85.
- Step 2: The class average (μ) is 75.
- Step 3: The standard deviation (σ) for the class is 5.
- Step 4: Let’s calculate: (85 – 75) / 5 = 2.0
→ Conclusion: Your Z-score is +2.0. This means you scored exactly 2 standard deviations above the class average. That’s a phenomenal score!
If your standard deviation (σ) is zero, it means every single data point in your set is exactly the same number. You absolutely cannot calculate a Z-score in this case because dividing by zero is mathematically impossible!
To make things even easier, I’ve put together a handy little interactive calculator for you below. Give it a try with some of your own numbers!
🔢 Linear Z-Score Calculator
Why We Really Use It 👩💻
So, why do we go through all this trouble? I truly think the biggest benefit lies in modern Machine Learning and advanced data analytics. When complex algorithms look at data, they don’t inherently understand that a $100,000 salary and 25 years of age are just different scales of measurement. To an algorithm, 100,000 is just massively larger than 25, which can completely ruin the model’s accuracy.
By applying a linear Z transformation, we perfectly level the playing field. This ensures that no single feature overpowers the others simply because of its original unit of measurement. It is foundational to models like Principal Component Analysis (PCA) and K-Nearest Neighbors (KNN)!
Linear Z-Score Summary
FAQ ❓
I truly hope this guide clears up the mystery around the Linear Z transformation for you. It’s a foundational tool that every data enthusiast, statistician, and machine learning engineer should keep safely in their back pocket! If you have any more questions, or if you want to share how you personally use Z-scores in your projects, feel free to ask in the comments below! 😊